RS Glossary
RLHF
RLHF stands for reinforcement learning from human feedback, a method that uses human preferences to help train a model toward more desirable responses.
- Review state
- Reviewed in POC
- Freshness
- Current
- Version
- 2
- RLHF
- Reinforcement Learning from Human Feedback
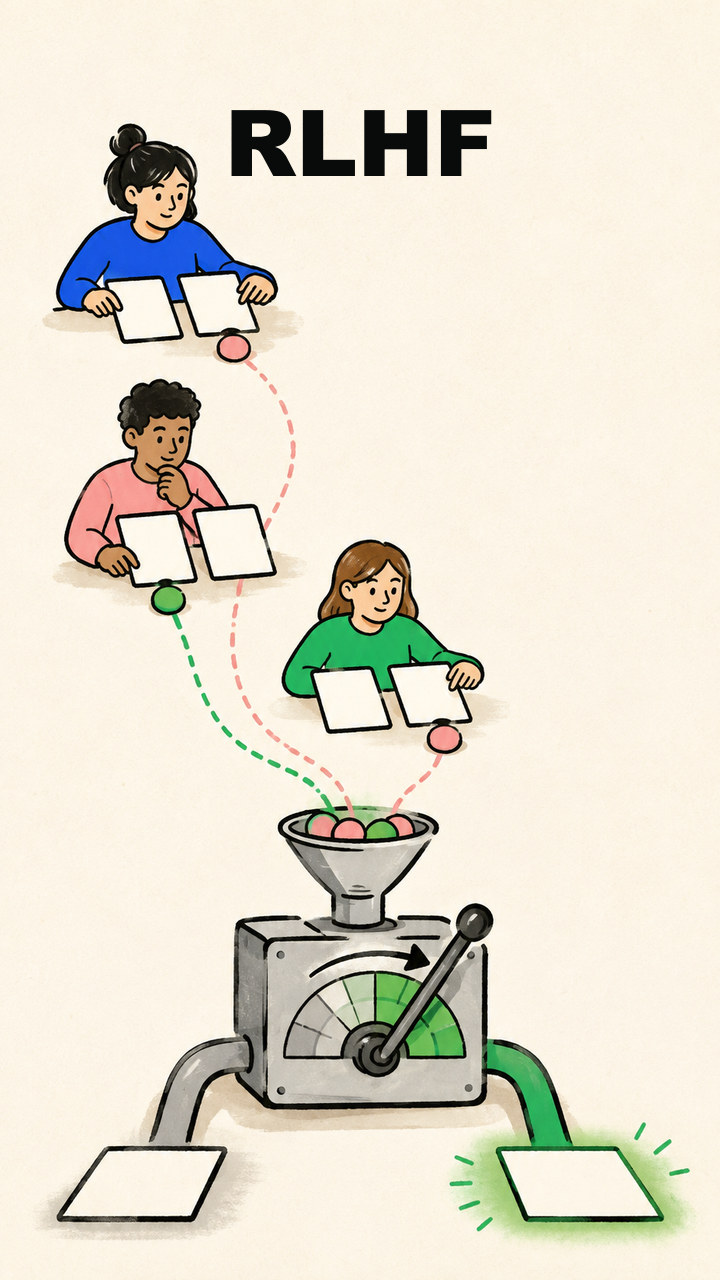
Remember it this wayHuman preferences train a reward; the reward steers the model.
In plain language
Reinforcement Learning from Human Feedback, or RLHF, uses human judgments to train a reward signal and then adjusts a model to produce outputs that score better under that signal.
Why it matters
RLHF can make outputs more useful or aligned with stated preferences, but the result reflects the reviewers, prompts, reward design, and optimization choices used in the process.
Example
Reviewers rank several answers to the same prompt. A reward model learns from the rankings, and reinforcement learning adjusts the language model toward higher-scoring responses.
Common misconception
RLHF does not give a model human values or eliminate harmful behavior. It optimizes against a learned approximation of selected human feedback.
Related terms
Sources
- Long Ouyang and colleagues, “Training Language Models to Follow Instructions with Human Feedback”documents supervised fine-tuning, reward-model training, and reinforcement-learning stages used in InstructGPT.
Learn more
- Compare [[alignment|Alignment]], [[human-review|Human Review]], [[fine-tuning|Fine-Tuning]], and [[direct-preference-optimization|Direct Preference Optimization]] to place RLHF in the surrounding system.
- Follow the cited source material above for the method, standard, or research context behind this draft.
Public history
23 recorded events · 23 public summaries
A potential shared concept was discussed and selected for initial glossary drafting.
The captured candidate received a complete initial draft and entered section-level human review.
Radar reviewed the initial definition draft for human consideration.
Radar reviewed the initial plain-language-explanation draft for human consideration.
Radar reviewed the initial why-it-matters draft for human consideration.
Radar reviewed the initial example draft for human consideration.
Radar reviewed the initial common-misconception draft for human consideration.
Radar reviewed the initial remember-it-this-way draft for human consideration.
Radar reviewed the initial related-terms draft for human consideration.
Radar reviewed the initial sources draft for human consideration.
Radar reviewed the initial learn-more draft for human consideration.
Definition review recorded as approve.
Plain-Language Explanation review recorded as approve.
Why It Matters review recorded as approve.
Example review recorded as approve.
Common Misconception review recorded as approve.
Remember It This Way review recorded as approve.
Related Terms review recorded as approve.
Sources review recorded as approve.
Learn More review recorded as approve.
Sources review recorded as replace.
Radar verified the learner-facing sources after personal origin provenance was removed.
All nine current wording approvals were reconciled to Approved term status.
Source: vault/Glossary/terms/rlhf/term.md · sha256:066cdcf116f10d575be4404a156170e6977171f6b9f1d0223dfb2ad551013745 · Release: rs-glossary-glossary-team-poc-0.5.5-2026-09-02